Today I want to talk about a feature that not many people used a few years ago, but now with Artificial Intelligence we cannot live without it if you work locally.
Imagine working on several features in parallel, on the same repository. This does not work well, because if you work in a single folder, everything steps on everything else. Three agents working in parallel are going to be touching each other's files, and for that Git has a solution: worktrees.
Before, they were not used that much, since the use cases were usually more like when you were going to review code or help someone, you had a worktree with your changes and switched to another one with the other person's changes. But as I said, nowadays, it is really necessary.
Table of contents
1 - What is a Worktree in Git?
Worktrees are a feature that lets us have several working folders associated with the same repository.
And to understand them we need to know how to differentiate between a branch, or rama if you say it in Spanish, and a folder. It seems simple and obvious, but it can get confusing, because a branch is the reference to a commit, and the folder contains the files that we are going to modify.
And when we switch branches, what Git does behind the scenes is change the files in that folder so we can work on the selected branch.
Having worktrees lets us have another separate folder, pointing to another branch but in the same repository.
To give an example, we can do it with my Distribt project, but this works anywhere.
Imagine you are adding a new service, and someone else is fixing a bug. You can be working on your main branch, task-1234, in the original folder. When your teammate asks you to review the bug on your machine to see if it is fixed, you can switch to that worktree, which behind the scenes will be called “bugs” or something similar, and put their branch in that worktree. In your file system you will also have a folder called “bugs” that references the worktree.
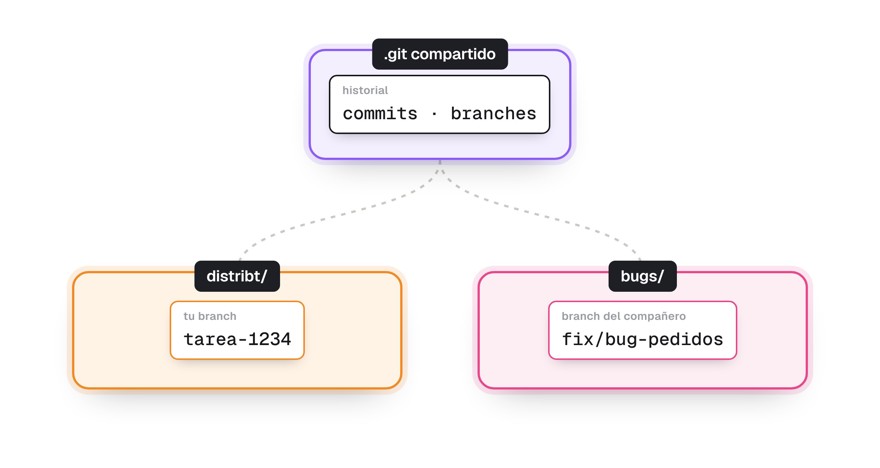
In this case I used an existing worktree, but it is also common to create one worktree per task. In that case, the bug itself could have its own worktree. Or if you are working with agents on multiple tasks at the same time, you can have something like this
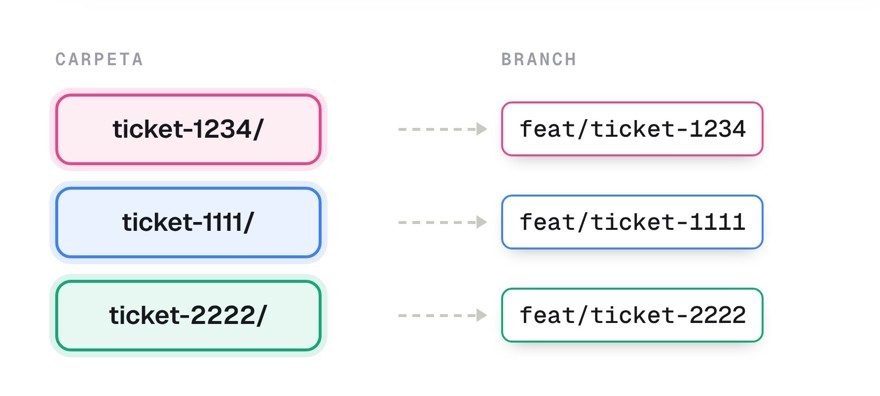
Under the hood, worktrees share Git objects, both commits and references to branches, but at the same time they contain their own HEAD, their staging area, and their different files. That is why you can prepare a change in one while checking something different in another without them affecting each other.
2 - Working with worktrees
Even though that was the main point of the post, and with AI you tell it to create a worktree and it runs the commands and that is it, I think it is important to be clear about, and understand, at least the key parts.
For this point we are going to look at our project from before. With the remote called origin and the main branch as main, which is the most normal setup if we have everything by default.
2.1 - Create a worktree
To create a worktree, let's put ourselves in the situation where we have merged something, and now we are going to work on ticket-123. We run the following commands in the terminal:
git fetch origin
git worktree add -b feat/ticket-123 ../ticket-123 origin/main
What did we do here?
The first command updated our information.
The second one has several parts to understand.
-b feat/ticket-123indicates that we want to create a new branch.../ticket-123is the folder where we are going to workorigin/mainis our starting point
And you cannot have the same branch active in two worktrees.
2.2 - Work with the new worktree
While it is true that some user interfaces, like GitHub Desktop itself, make life much easier, in the terminal it is not much more complicated.
We have just created our worktree and, to work in it, what we need to do is enter it. To do that, we simply go into the folder
cd ../ticket-123 And that's it, we can work as usual, make our changes, and push.
git add .
git commit -m "example message"
git push -u origin feat/ticket-123
And from here we can create a completely normal pull request.
2.3 - Remove worktrees
You created the PR, and it has been merged. Just do not ignore that folder with the files or leave it abandoned on your computer, because in the end they will become many, many gigabytes and they will clog up your disk.
What we need to do is remove the worktree.
To do that, it is as simple as, while being outside the worktree folder, running the following command
git worktree remove ../ticket-123
This command removes both the folder and its record as a worktree. The branch feat/ticket-123 still exists, so we also have to run a command for that:
git branch -d feat/ticket-123Careful, do not perform these actions before merging the pull request.
2.4 - Review other branches without affecting our work
Another very common tool, which I already mentioned before, is checking someone else's work, but we do not want this to affect us. For that we are going to use the option --detach, which leaves that worktree at a specific commit without leaving an active local branch.
To do this, we run the following command:
git worktree add --detach ../ticket-999 origin/feat/ticket-999
Now we can open the project, run the tests, and check how it works while we keep our development in the other folder.
Careful, this points to a specific commit. If later that ticket-999 branch has changes, it does not update automatically. Just run a fetch and execute Git's switch command:
cd ../ticket-999 <-- (la carpeta del ticket que estamos mirando)
git fetch origin
git switch --detach origin/feat/ticket-999
That way it goes back to the latest commit of the remote branch.
3 - What each folder or worktree contains
You might think that what we have just done is have several completely independent environments, and that is not the case, because the only thing we are doing is separating the working environments. The rest of the configuration will depend on how the application is set up.
For example, if you have a file ignored by Git, as .env usually is, it is not copied to the new worktrees. The same happens with dependencies or the files resulting from a build in .NET. When creating the worktree, you have to do another full build.
Of course the same applies to the configuration. If you have it set up to listen on a specific port, and you start two applications, both will try to use the same port, call the same database, etc. I imagine you get the idea.
To run versions in parallel, we will have to set up all the infrastructure and configuration needed to allow that functionality, although with aspire it is quite a bit simpler nowadays than it was a few years ago.
Conclusion
Before the arrival of AI, using worktrees could be useful for specific situations, since very few people worked on two or three tasks simultaneously. Nowadays it seems to me like something we need to use in our day to day.
Comments